Mini Code Assistant
I trained the Qwen3 model using fine-tuning as a Python coder.
In this example, I fine-tuned the Qwen3 1.7B model on Python coding instructions by combining the iamtarun/python_code_instructions_18k_alpaca and flytech/python-codes-25k datasets.
The question
Can I improve the accuracy of solving Python algorithm problems by fine-tuning the Qwen3 model?
Approach
- 68,238 training examples
- 3412 test, 3412 validation and 61,414 train set
- Qwen3 1.7B as base model
- unsloth for gpu efficiency and speed up the train
Result
I retrained the Qwen3 1.7B model using Python code and instructions and ran benchmarks on it. I spent $3 on 4 epochs, and in the benchmark consisting of 100 questions, it answered 2 more questions than the Qwen3 1.7B base model; however, the biggest difference was that while my fine-tuned model provided answers within a few seconds, the base model took a long time to think.
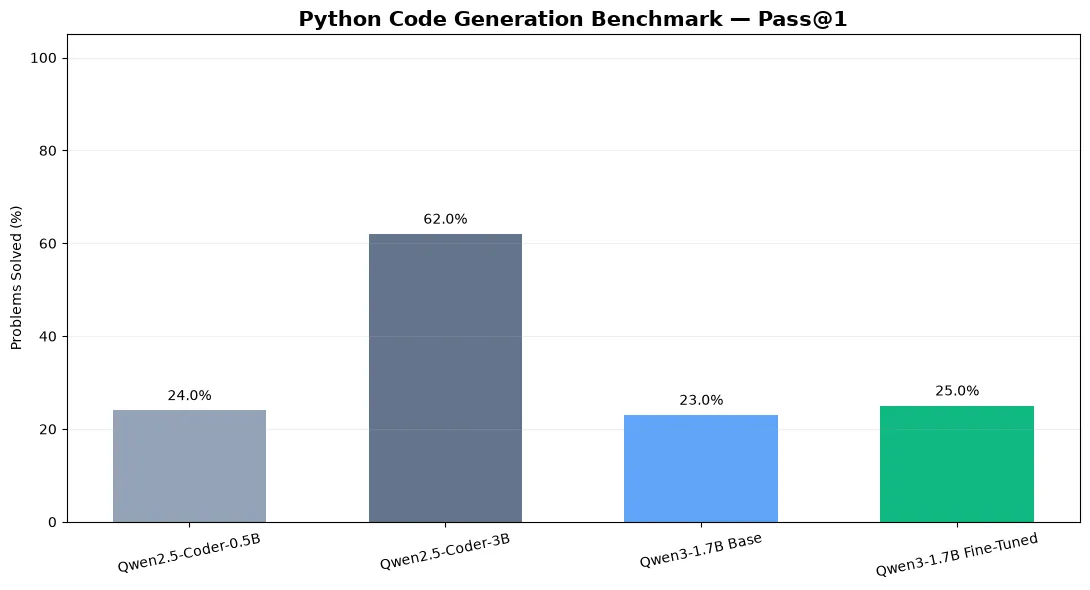
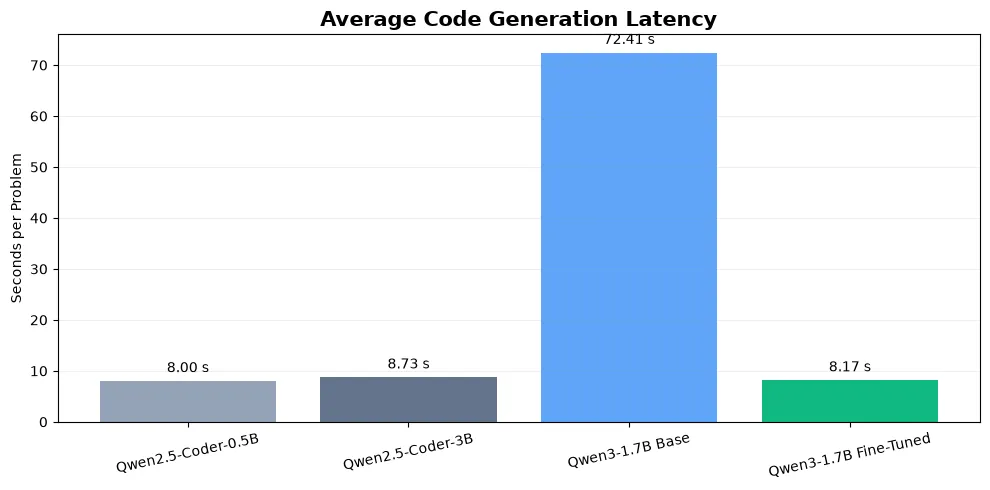
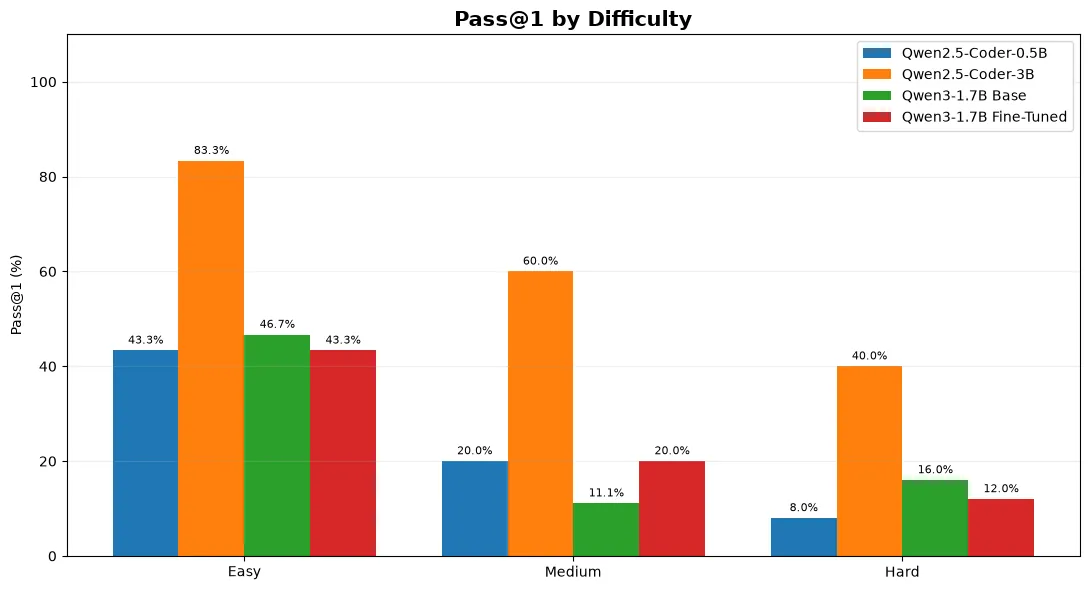
These tables clearly show that the model I trained has achieved a very high level of acceleration and can generate code at the same speed as Coder models trained on gigabytes of data; however, it’s important to note that while it produces responses more quickly, this does not affect the accuracy of the responses. The chart below compares the percentage of questions solved by difficulty level. If you’d like to try out the model, you can do so using Gradio at the bottom of the page.
What I Learned
- I realized that a GPU is definitely not a cheap resource and just how essential it is.
- I experienced firsthand how Unsloth’s optimizations reduced the VRAM consumption—which had previously been very high—to just a few GB.
- I understood that finding data and running benchmarks are just as important as training a model, and why that is.
- I learned how to combine different datasets into a single dataset.
Downloads
- Benchmark 100 Python Question - Chatgpt Generatedpython100_full.json · 204.8 KB
- Qwen3 1.7B - Benchmark Resultsbase-1.7B_results.json · 82.4 KB
- Qwen2.5 0.5B Coder - Benchmark Resultscoder-0-5B_results.json · 158.6 KB
- Qwen2.5 3B Coder - Benchmark Resultscoder-3B_results.json · 130.2 KB
- Fine-tuned Qwen3 1.7B - Benchmark Resultsfinetuned-1.7B-code-assitant_results.json · 132.1 KB
Demo
Open demo ↗Owner’s ZeroGPU quota: checking remaining time…
This is the owner’s personal allowance, not a shared visitor balance. Your Hugging Face account or guest session has its own quota; its exact remaining time is shown by Hugging Face. CPU demos do not use ZeroGPU time.
The demo loads only when you choose to open it. It may need time to wake up.